Turn sensitive unstructured data into training-ready data
Tonic Textual finds sensitive information across your documents, transcripts, and files, then redacts it or replaces it with realistic synthetic values. Use your data safely for AI development, analysis, and sharing, while keeping the signal that makes it valuable.



Licensing company data to AI labs?
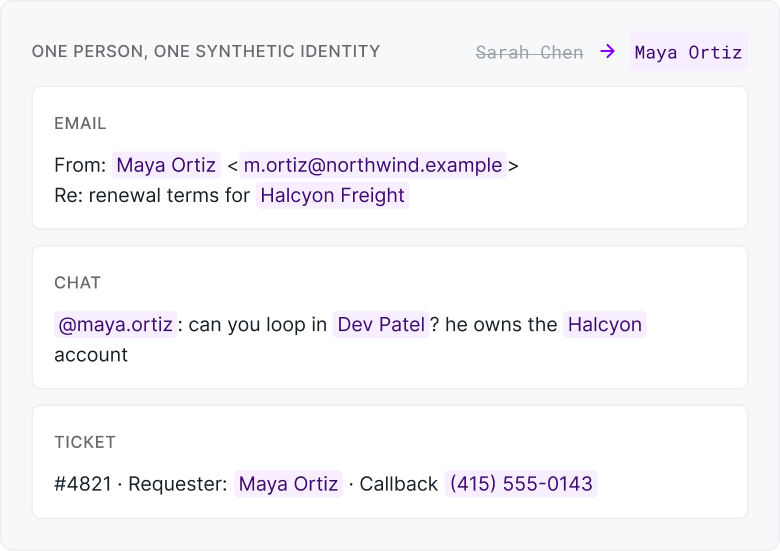
Frontier labs won't accept company data until the people in it are de-identified. Tonic de-identifies email, chat, tickets, and documents at corpus scale, giving every person one synthetic identity that stays consistent everywhere it appears.
Sensitive information scrubbed with an audit trail and a human in the loop on every dataset
Consistent synthetic replacements that maintain relationships across systems and preserve the data's value for training
Turnaround in days, with certification by Tonic.ai or a third party
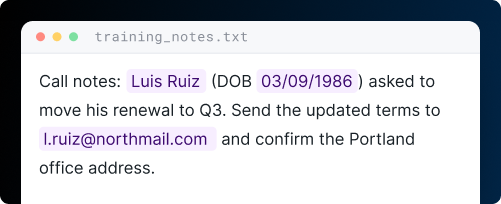
AI model training and development
Train and fine-tune models on clinical notes, transcripts, and documents without exposing the people in them. Realistic synthetic values keep the context your models learn from.
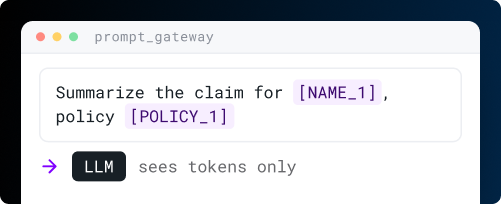
LLM privacy proxy
Scrub sensitive values from text on its way into a prompt or pipeline, so private information stays out of third-party models and the workflows built on them.
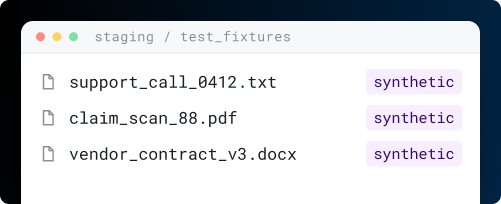
Development and testing
Give developers realistic documents, transcripts, and files in dev and test environments, so they can build AI features without touching production data. Pair Textual with Tonic Structural to de-identify the databases alongside them.
Detection you can tune. Synthesis you can train on.
Tonic Textual's proprietary NER models find the sensitive information in your text and files. Realistic synthetic values replace it, so your data keeps the signal your models learn from.
Detection tuned to your data
After Textual’s initial scan, an LLM check removes false positives, so only truly sensitive values get replaced. For proprietary identifiers like project codenames or internal account formats, train custom entity types on examples from your own data to catch what’s sensitive to your business.
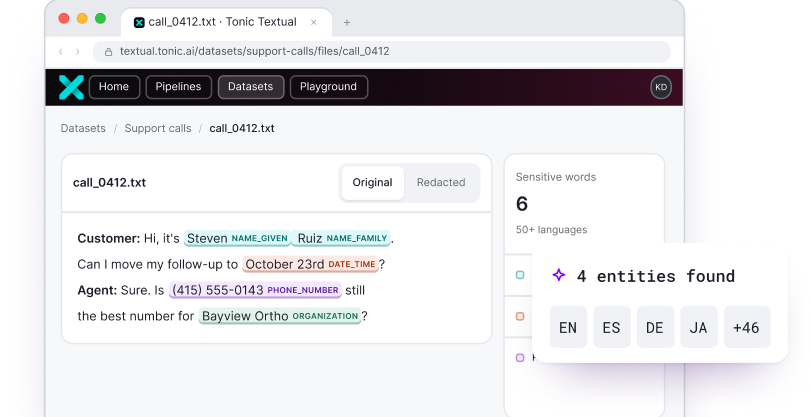
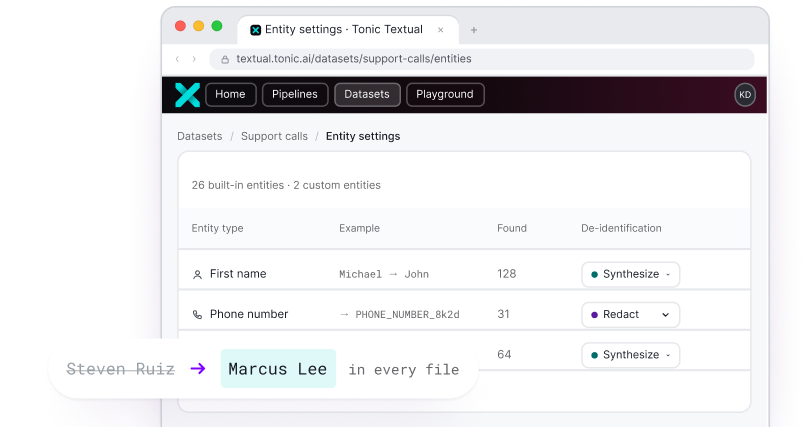
Consistent synthesis across files
Textual replaces each sensitive value with the same synthetic value every time it appears, across every file in your dataset. A name that shows up in an email, a PDF, and a spreadsheet gets the same replacement in all three, so references still line up and your data stays usable for training, analysis, and sharing.
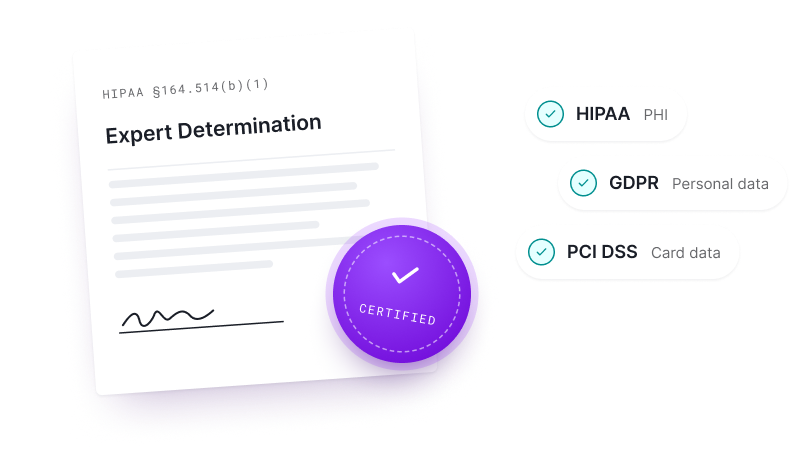
Designed for compliance
Textual helps teams meet HIPAA, GDPR, and CCPA obligations by removing PII and PHI before data is used, shared, or trained on. For healthcare data, Tonic.ai’s de-identification meets HIPAA requirements, with certification through an independent Expert Determination partner.
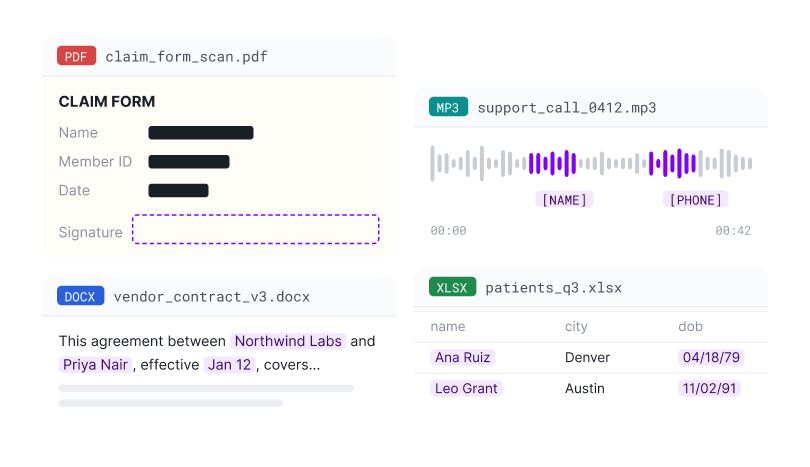
Every document and conversation
Textual handles virtually every unstructured format, from free text and PDFs to Office files, transcripts, and audio. It even finds values in scanned forms and detects logos and signatures, turning your hardest documents into privacy-protected assets ready for downstream use.
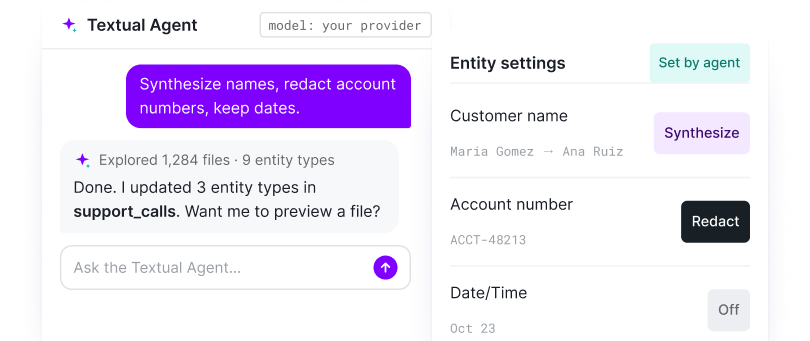
Configuration by conversation
Tell the Textual Agent what you need in plain language, and it explores your datasets and sets up how each entity type is handled. Your team gets to a working configuration faster, without learning every setting first, on the model provider you choose.
See Tonic Textual protect your data inside your AI workflow
Accuracy you can check for yourself
PrivacyBench is Tonic.ai's open benchmark for end-to-end de-identification of email, chat, and document exports, with public datasets and public scoring code.
End-to-end score • #1 of 7
In PrivacyBench, Tonic led seven de-identification pipelines end to end, 5.2 points ahead of the best frontier-LLM pipeline.
Best frontier-LLM pipeline • 80.1%
PII-detection F1
Textual's PII-detection F1 against human-annotated data, the highest of any engine tested.
Wellthy
Wellthy saw a 50% reduction in flagged care team actions and expanded its AI development capability with Textual.
Ontra
Textual is foundational to Ontra's AI strategy, consistently de-identifying and synthesizing structured and unstructured data for safe, scalable AI innovation in legal tech.
Your data, in every format, ready to use
Tonic Textual unlocks unstructured enterprise data however and wherever it's stored. Bring it in through the UI, the Python SDK, or the API.

CSV
.txt
XML
HTML
JSON
.pptx
.docx
.png
.jpeg
.xls
+ more
Deploy Textual on the cloud or self-hosted
Accessible where your data lives
Connect Tonic Textual to Amazon S3, Google Cloud Storage, and Azure Blob Storage, or use Textual Cloud, hosted by Tonic.ai.


Available through your cloud provider
Burn down your cloud commitments by procuring Textual through the Snowflake Marketplace, AWS Marketplace, and Google Cloud Marketplace.


Or deploy self-hosted
Run Textual in your own environment with Kubernetes or Docker when your data can't leave your infrastructure.

Guides and playbooks for sensitive unstructured data
Deep dives, how-tos, and playbooks on finding and protecting sensitive information in text, documents, and audio, including how teams prepare AI training data.







Synthesizing healthcare data for AI model training, with HIPAA Expert Determination


Understanding data redaction: Use cases, benefits, and how to automate redaction workflows

What is retrieval augmented generation? The benefits of implementing RAG in using LLMs


How to prevent data leakage in your AI applications with Tonic Textual and Snowpark Container Services


Frequently asked questions
Tonic Textual is AI-powered redaction and synthesis software for unstructured data. It detects sensitive information in free text, documents, and recordings with proprietary NER models, then redacts it or replaces it with realistic synthetic values. Teams use the output for model training, analysis, testing, and sharing. The Textual documentation covers setup and workflows.
Against human-annotated data in Tonic.ai's PrivacyBench v2 benchmark, Tonic Textual posted the highest PII-detection F1 of any engine tested, 92.5%, ahead of frontier LLMs from OpenAI and Anthropic and the open-source tools Presidio and GLiNER2. Detection pairs NER models with an LLM check that removes false positives. See the full PrivacyBench results.
Yes. Textual replaces each sensitive value with the same synthetic value every time it appears, across every file in a dataset. A name in an email, a PDF, and a spreadsheet gets the same replacement in all three, so references still line up after de-identification. If you also use Tonic Structural, synthesized addresses and US phone numbers can match across both products. See the synthesis options docs.
Textual handles plain text, PDFs, scanned images, Word, Excel, PowerPoint, CSV, JSON, XML, HTML, and audio. It finds values in PDF forms and scanned documents, detects logos and signatures, and synthesizes PDFs in several languages while matching the original fonts. The Textual documentation lists every supported format.
Yes. Tonic.ai works with an independent Expert Determination partner, so data de-identified with Tonic.ai can be certified as de-identified under HIPAA's Expert Determination method, through a single engagement. The expert certifies the specific de-identified dataset, not the software. Learn how Expert Determination works.
Yes. Textual deploys self-hosted with Kubernetes or Docker, so sensitive data never has to leave your infrastructure and stays under your own security controls. It integrates with Amazon S3, Google Cloud Storage, and Azure Blob Storage, giving you full control over where data is processed and stored. See the self-hosting docs.
Yes. With Custom Entity Types, you train Textual to detect new categories, such as project codenames or internal ID formats, from examples of your own data, with no data science expertise required. For forms, form label mappings tag field labels with entity types so matching values are found. Learn more about custom entity types.